分类 默认分类 下的文章

JVM 的 TimeZone 被别人改了

昨天有同事让我看看为啥一台QA的机器上的时区变了, 同样的代码在生产环境显示的日期都是 MST 时区(如:Tue Dec 06 06:52:22 MST 2022), 可是QA 环境显示的时间都是 UTC 时区(如: (如:Tue Dec 06 013:52:22 UTC 2022)).

检查步骤:

首先确认这个 Linux 机器上的时区

$ date
Tue Dec 06 013:52:22 UTC 2022

通过以上代码确认, 这个Linux 机器时区是正确的

检查 JVM 的时区

  1. JVM 可以通过启动参数添加: -Duser.timezone="XXXX/YYYY"

    java -Duser.timezone="Asia/Kolkata" com.tianxiaohui.AppMain
  2. 又或者设置系统环境变量添加

    System.setProperty("user.timezone", "Asia/Kolkata");
  3. 又或者通过设置默认时区:

    TimeZone.setDefault(TimeZone.getTimeZone("UTC"));

对于第一种方式, 可以通过检查Java 进程的启动命令获得(这里假设pid是44848), 发现命令行没设置时区.

cat /proc/44848/cmdline
````
对于第二种方式, 我们首先通过查 看 ```cat /proc/44848/environ``` 的方式去查看, 没发现这个环境变量. 不过我们通过jdk 自带的命令的方式却发现了:

$ bin/jcmd 44848 VM.system_properties
java.version=1.8.0_342
user.timezone=America/Phoenix
sun.arch.data.model=64

虽然找到了系统环境变量, 却发现这里是正确的, 并不是Date.toString() 表现出的UTC 时区. 于是就只能检查是不是第三种设置的. 

# 如何查看当前运行中的JVM里面的默认时区
1. 可以通过 JVM attach agent的方式去查看, 要自己写个 Agent, 可以参考这个简单的 Agent: https://github.com/manecocomph/myJavaAgent/blob/962f424176e02b9638fec87a0a5d1bad9cfaf0b2/src/com/tianxiaohui/java/agent/SampleAgent.java
当然, 你可以通过 Btrace 不安全的方式,找个容易控制的拦截点, 然后打印 默认时区. 

2. 另外一种方式就是直接做一个heap, 直接查看heap 里面的 Timezone 找个class的字段, 我们就采取了这种方式, 打开 heap dump, 找到这个 java.util.TimeZone 类, 然后查看其静态字段defaultTimezone, 直接可以看到被设置的时区. 
第一步找到这个类:
![heap1.png][1]
查看其 静态字段 defaultTimeZone
![defaultTZ.png][2]

# 找到代码
既然确认是通过代码设置默认时区, 那么直接搜索代码就找到了. 原来他们在最近的代码改动中, 有人为了某个feature, 直接修改了系统 TimeZone, 但是其本来只是想看看另外一个时区的时间. 


[1]: https://www.tianxiaohui.com/usr/uploads/2022/12/2240322561.png
mongo express MongoError: command listCollections requires authentication

为了连接一个MongoDB server 省事, 不想装本地app, 于是想使用docker 装一个 Web 版本的 Mongo express. 在启动的时候, 总是报这个错: MongoError: command listCollections requires authentication

我的连接URL是: mongodb://user1:[email protected]:27017/test_db. 可是根据官方的说明, 不论怎么写 docker command 都不行.

$docker run --rm -e ME_CONFIG_MONGODB_SERVER=mymongo.tianxioahui.com \
                 -e ME_CONFIG_BASICAUTH_USERNAME=user1 \
                 -e ME_CONFIG_BASICAUTH_PASSWORD=pwd1 \
                 -e ME_CONFIG_MONGODB_ENABLE_ADMIN=false \
                 -e ME_CONFIG_MONGODB_AUTH_DATABASE=test_db
                 -p 8083:8081 --name myMongo  mongo-express

(node:6) UnhandledPromiseRejectionWarning: MongoError: command listCollections requires authentication
    at Connection.<anonymous> (/node_modules/mongodb/lib/core/connection/pool.js:453:61)
    at Connection.emit (events.js:314:20)
    at processMessage (/node_modules/mongodb/lib/core/connection/connection.js:456:10)
    at Socket.<anonymous> (/node_modules/mongodb/lib/core/connection/connection.js:625:15)
    at Socket.emit (events.js:314:20)
    at addChunk (_stream_readable.js:297:12)
    at readableAddChunk (_stream_readable.js:272:9)
    at Socket.Readable.push (_stream_readable.js:213:10)
    at TCP.onStreamRead (internal/stream_base_commons.js:188:23)

可是不论怎么调可用的参数, 总是报这个错. Google 了一下, 发现2021年6月就有人报这个错: https://github.com/mongo-express/mongo-express/issues/720

解决方式也很简单, 直接用一个连接URL 替换其他环境变量:

sudo docker run --rm -e ME_CONFIG_MONGODB_URL=mongodb://user1:[email protected]:27017/test_db  -p 8083:8081 --name myMongo mongo-express

可是, 可是, 这个环境变量ME_CONFIG_MONGODB_URLhttps://hub.docker.com/_/mongo-express 竟然没有, 可是能用, 还很管用.

xxx Is Damaged and Can’t Be Opened. You Should Move It To The Trash

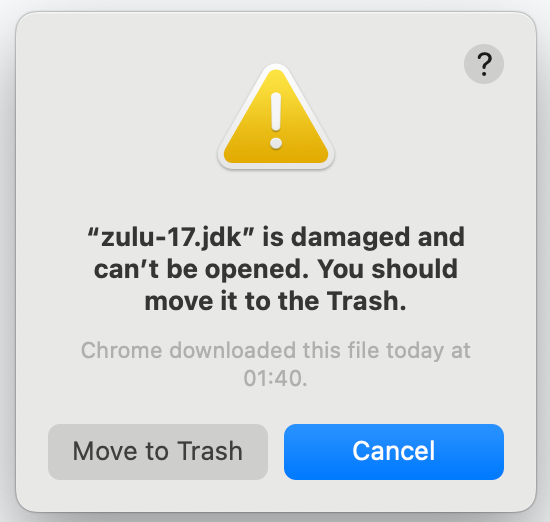
最近拿到公司 ARM 芯片的 Mac Pro, 一番设置, 可是新新下载的软件, 比如JDK, 总是报下面的错, 无法运行:
“xxx Is Damaged and Can’t Be Opened. You Should Move It To The Trash“
damage.png

如何修复

google 到这个修复方法: https://discussions.apple.com/thread/253714860

$ xattr -c <path/to/application.app>

使用上面的方法对 java 做上述操作, 还是一样的错误, 一度怀疑这个不行. 但是通过 xattr 查询它的属性, 发现又是相关. 最终发现这么解决: 对目录里面每层文件都做这个操作:

eric@Q67J490MY0 bin % pwd
/Users/eric/work/tools/jdks/jdk17.0.3.1/bin
eric@Q67J490MY0 bin % xattr -c *
eric@Q67J490MY0 bin % cd ..
eric@Q67J490MY0 jdk17.0.3.1 % xattr -c *
eric@Q67J490MY0 jdk17.0.3.1 % ./bin/java

上面的操作是对每个文件都去掉xattr的那些属性.

更多

xattr -h #查看帮助

python 使用 cProfile 做 profiling

最近开始看机器学习的项目, 于是开始看 Python 的代码. 把一个机器学习的模型发布上 prod 去预测结果, 发现生产环境里面 的性能很差: 本地 1s 能跑完的 API, 在生产环境需要 30 多毫秒. 先是看了下基本情况, 发现生产环境在预测那段代码, 竟然起了 50 多个 Python 线程. 于是怀疑生产环境因为使用 container, 但是却拿到了宿主机的 CPU 数量, 于是开了很多线程. 但是 container 却限制了 cpu 的使用量, 导致多线程竞争, 最终性能下降.

于是尝试做 profiling: cProfile 是python 自带的.

要做 profiling 的部分:

import os
import time
import cProfile
from transformers import BertTokenizer, BertModel

pretrained_model_path = os.path.abspath(os.path.dirname(__file__)) + '/bert-base-uncased'
bert_tokenizer = BertTokenizer.from_pretrained(pretrained_model_path, cache_dir='/tmp')
bert_model = BertModel.from_pretrained(pretrained_model_path)

s = "This brings us to the downsides"

def bert_function():
    t0 = time.time()
    for i in range(0, 10):
        inputs = bert_tokenizer(s, return_tensors="pt")
        outputs = bert_model(**inputs)

    print("used: {}".format((time.time() - t0)))

cProfile.run('bert_function()', 'my.prof')

执行

python test.py

使用 flameprof 转成 火焰图

python -m flameprof my.prof > my.svg

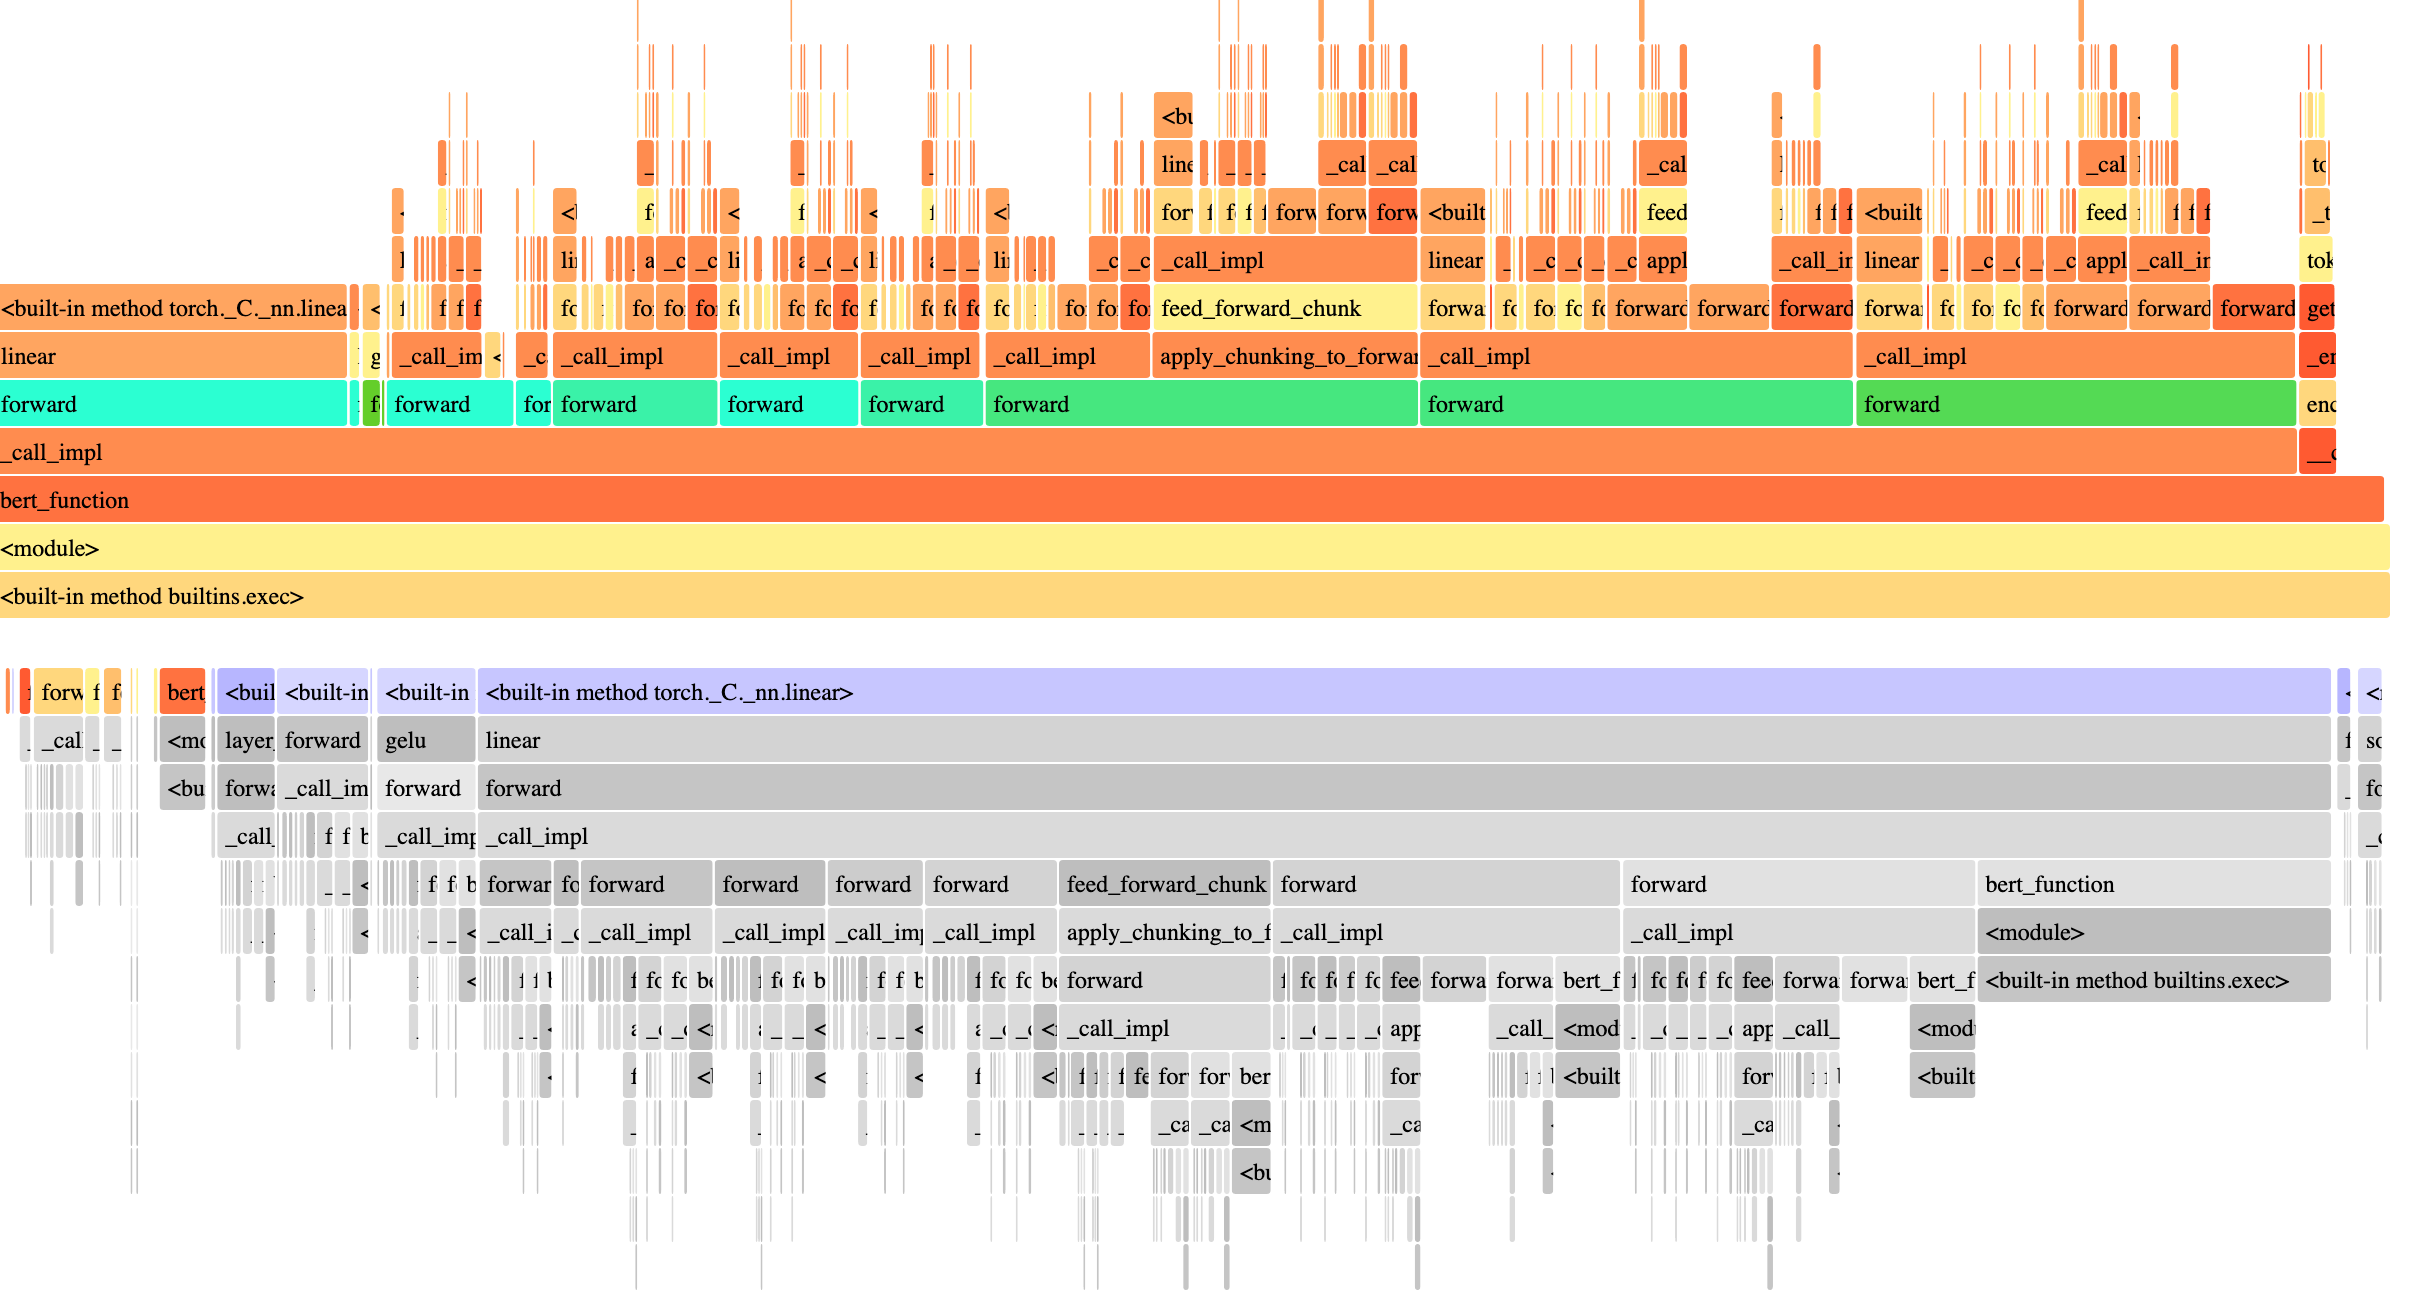
结果:
out_svg.png

参考:
https://docs.python.org/3/library/profile.html

Prometheus 学习笔记

Introduction

Overview

  1. Prometheus is an open-source systems monitoring and alerting toolkit.
  2. Prometheus collects and stores its metrics as time series data, i.e. metrics information is stored with the timestamp at which it was recorded, alongside optional key-value pairs called labels.
  3. Features

    1. a multi-dimensional data model with time series data identified by metric name and key/value pairs
    2. PromQL, a flexible query language to leverage this dimensionality
    3. no reliance on distributed storage; single server nodes are autonomous
    4. time series collection happens via a pull model over HTTP
    5. pushing time series is supported via an intermediary gateway
    6. targets are discovered via service discovery or static configuration
    7. multiple modes of graphing and dashboarding support
  4. Components

    1. the main Prometheus server which scrapes and stores time series data
    2. client libraries for instrumenting application code
    3. a push gateway for supporting short-lived jobs
    4. special-purpose exporters for services like HAProxy, StatsD, Graphite, etc.
    5. an alertmanager to handle alerts
    6. various support tools
  5. Prometheus configuration file: prometheus.yml

    1. global.scrape_interval
    2. global.evaluation_interval
    3. rule_files: []
    4. scrape_configs: {job_name:"", static_configs:""}
  6. Prometheus server UI

    1. status page: http://:9090/
    2. self metrics page: http://:9090/metrics
    3. expression browser: http://:9090/graph
  7. glossary

    1. The Alertmanager takes in alerts, aggregates them into groups, de-duplicates, applies silences, throttles, and then sends out notifications to email, Pagerduty, Slack etc.

Concepts

  1. Data models

    1. <metric_name>{<label_name>=<label_value>, ...}
    2. metrics_name 符合: /a-zA-Z_:*/ 字母数字下划线分号(分号只是用在定义 recording rule 的)
    3. dimensional(维度)需要通过 labels 定义
    4. time series: streams of timestamped values belonging to the same metric and the same set of labeled dimensions.
    5. 添加/去除等改变 label value 的操作会导致创建新的 time series
    6. label name 符合 /a-zA-Z_*/ 字母数字下划线 (2个连续下划线(__)开头的 label name 是系统保留用的)
    7. label value 可以使用任何 Unicode 字符
    8. A label with an empty label value is considered equivalent to a label that does not exist
  2. Metrics Types

    1. Counter: 单调增长的计数器, 重启后变为0再自增
    2. Gauge: 可增可减的数值
    3. Histogram: 柱状图 指标 basename
    1. _bucket{le=""}
    2. _sum: total sum
    3. _count: =_bucket{le="+Inf"}

      1. Summary
  3. Jobs & Instances

    1. When Prometheus scrapes a target, it attaches some labels automatically to the scraped time series which serve to identify the scraped target: job: <job_name> & instance: :

    Prometheus

  4. Configuration

    1. command-line flags configure immutable system parameters (such as storage locations, amount of data to keep on disk and in memory, etc.)
    2. configuration file defines everything related to scraping jobs and their instances, as well as which rule files to load.
    3. Prometheus can reload its configuration at runtime.
    1. send SIGHUP;
    2. HTTP POST request to the /-/reload endpoint

      1. scrape_config
    3. Targets with static_configs or dynamic service-discovery;

      1. rule check -> promtool check rules /path/to/example.rules.yml
  5. PromQL

    1. can evaluate: instant vector, range vector, scalar, string
    2. metrics_name{} 可以写为: {__name__="metrics_name"} 比如查询多个 metrics {__name__=~"job:.*"}
    3. subQuery: <instant_query> '[' ':' [] ']' [ @ <float_literal> ] [ offset ] ( is optional. Default is the global evaluation interval.)
    4. Vector matching
    1. ignoring(
    2. on(
  6. Storage

    1. format: https://github.com/prometheus/prometheus/blob/release-2.36/tsdb/docs/format/README.md